中 / EN

Decoding Algorithms

251 entries

Neural signal decoding is the technical core of brain-computer interfaces, translating brain electrical activity into executable commands or intelligible language. This topic covers algorithm advances in motor imagery classification, speech decoding, and attention detection, along with engineering challenges such as transfer learning and online adaptation.

September 2026

Notre Dame Team Lets BCIs Hold Back Uncertain Commands, Cutting Errors to 9–16%

When a motor imagery BCI is used on a different day, EEG signals drift, yet a standard classifier keeps issuing commands regardless of confidence. Researchers at the University of Notre Dame, reporting in the Journal of Neural Engineering, added a conformal prediction gate that withholds commands when the model is unsure. Using DeepConvNet as the base classifier, the gate cut the share of wrong commands from 37.5% to 9–16% on the OpenBMI dataset (54 subjects) and from 35.5% to 6–8% on BCI Competition IV Dataset 2a (9 subjects), at the cost of issuing fewer commands. All results come from offline public datasets.
Bishop’s University Finds Individual Visual Decoding Differences Depend on the Instrument

Researchers at Bishop’s University compared visual decoding using EEG, MEG, intracranial EEG, and fMRI. Individual differences were reproducible within an instrument, but external paired cohorts did not show a common participant ranking across instruments. Classifiers were tested on recording runs and stimulus identities excluded from training. Attention, behavior, and peripheral signals affected recording quality but did not explain most stable differences. Intracranial recordings also linked sharper local category selectivity to easier decoding. The authors interpret these differences as reflecting the relationship between the individual, the distinction being represented, and the instrument, rather than a fixed personal trait alone.

Peking University Collaboration Reconstructs Movie Frames From Optogenetically Stimulated Mouse Cortex

A collaboration involving Peking University converted dynamic natural movie frames into spatiotemporal patterns of optogenetic stimulation in awake mice, then reconstructed movie frames from responses in the primary visual cortex. Comparing natural viewing with artificial stimulation, they found that stimulation evoked broadly comparable cortical dynamics and aligned representations. A deep learning model reconstructed frames from cortical signals under both conditions. The animal study offers a proof of concept for evaluating how visual cortical prostheses might translate images into stimulation patterns. It does not establish that stimulation produced the corresponding visual experience in mice or restored vision in humans.

ThinkNet Closes EEG Test Leaks, Finds Accuracy in the 40s and Small Models Ahead

Researchers have proposed ThinkNet, a framework that keeps a test subject's data out of every decision, from data normalization to model selection and ensembling, so that EEG decoding scores for new users are not inflated. A BCI meant for new users must read their imagined limb movements from EEG without having seen their data. On the four-class task of the public BCI Competition IV-2a dataset, using 9-fold leave-one-subject-out cross-validation, the selected compact model, with only 4.9K parameters, reached 44.35±15.41% accuracy at 0.99 ms per inference. Small models of up to 25K parameters averaged 40.10%, above medium and large models at 35.09% and 34.78%, and validation-gated ensembles outperformed single-model inference. The team also found almost no correlation between validation and test scores, leaving reliable model selection a bottleneck. The study is a preprint and has not been peer reviewed; the authors note it has been accepted at the IEEE-EMBS BHI'2026 conference.

Preprint: Hosted Jev Model Matches 7B LLMs in Speech BCI Rescoring Without a GPU

Gabriele Cinà reported in an arXiv preprint posted on September 27, 2026, that Jev, a hosted model, can replace the multi-billion-parameter language model that speech neuroprostheses use to rescore candidate sentences, the only GPU-dependent step in the system. Jev returns a probability for each candidate in one call, which is combined with the decoder's own score. On 978 held-out sentences from a participant with ALS, the published decoder alone had an 8.1% word error rate, versus 7.5% with Jev and 7.8% with both OPT-6.7b and Qwen2.5-7B; after re-tuning decoder weights, the figures were 6.9%, 7.2% and 7.4% respectively. Jev needs no GPU, costs $0.07 per thousand sentences, and has 262 ms end-to-end latency over the internet, versus 27 ms for a 7B model on a local GPU. The work is a preprint and has not been peer reviewed.

Tianjin Team's Five-Color Flicker BCI Reaches 93.72% Accuracy on 64 Targets

Researchers at Tianjin University of Technology and Education in northern China built a 64-target visual evoked potential brain-computer interface that encodes stimuli as relative changes among five colors (red, green, blue, yellow and gray) with grouped modulation, replacing the high-contrast black-and-white flicker that tires the eyes and limits the number of options. Their decoder uses task-discriminant component analysis (TDCA) to extract target-related components from EEG, then classifies them with a lightweight multilayer perceptron (MLP). In experiments with 10 participants conducted from April to June 2026, the TDCA-MLP algorithm averaged 93.72% accuracy, outperforming 4 commonly used algorithms. The authors say the system requires less calibration and offers a better subjective viewing experience.

Tianjin University Team Review Maps Lightweight Motor Imagery BCI Decoders for Wearables

A review by a team including Tianjin University sorts ways to slim down deep-learning decoders for motor imagery EEG, which are accurate but too large for wearable devices, into two routes: redesigning convolutional neural networks (depthwise separable, multi-branch and dilated convolutions, attention mechanisms) and compressing existing models (pruning, quantization, knowledge distillation, low-rank decomposition). It compares representative lightweight models on parameter count, computational cost and classification accuracy, and recommends shifting toward automated neural architecture search and hardware-software co-design.

Shandong Researchers' EEG Network Decodes Motor Imagery at 96.41% on Benchmark Data

Researchers at Shandong University of Traditional Chinese Medicine in eastern China and partner institutions have developed DMB-EDN, a dynamic multi-branch network for decoding the faint scalp EEG changes that occur when a person imagines moving a hand or foot, the basis of non-invasive brain-computer interfaces. Its 3 branches capture temporal dynamics, time-frequency features and specific rhythms, and the network reweights them automatically for each trial. On the public BCI Competition IV 2a dataset it achieved 96.41% average accuracy (kappa 0.952); on the team's own data from spinal cord injury patients, tested on patients not used in training, it reached 85.00% accuracy (kappa 0.700). All results are offline, and the researchers say validation in larger multicenter populations and real-time online systems is still needed.

Researchers Fuse fMRI and MEG to Decode Heard Speech Across Subjects

Researchers have proposed SICMD, a method that combines two non-invasive brain signals, functional magnetic resonance imaging (fMRI) and magnetoencephalography (MEG), to identify speech a person is hearing from brain activity with a single model that works across different people. fMRI pinpoints where activity occurs and MEG captures when, together giving fuller spatiotemporal information. In cross-subject perceived-speech decoding, the method improved Top-1, Top-10 and Rankacc by more than 10.6%, 10.1% and 1.7% over baseline methods, and cut training costs by 88.8% and 60.5% compared with multi-subject and intra-subject decoding respectively. The work is a preprint and has not been peer reviewed.

Researchers Find Language Models Aid Imagined Speech More Than Heard Speech in MEG

Researchers have shown that language models do more to help decode imagined speech than heard speech from non-invasive brain recordings. Imagined speech is harder to read than speech a person hears: the brain's response is weaker and noisier, and less data is available. Using a magnetoencephalography (MEG) dataset in which participants both listened to and imagined the same material, the team brought a language model into both training and decoding. Imagined speech gained more from the model than heard speech, and its best results required leaning more heavily on the model. The authors conclude that the weaker the neural evidence, the more useful a language model's contextual prior becomes. The study is a preprint and has not been peer reviewed.

Cambridge Team Decodes Multidimensional Meaning From Combined 4–200 Hz Cortical Signals

A collaboration involving the University of Cambridge analyzed surface electrocorticography recordings from the human ventral anterior temporal lobe. It found significant decoding of graded, multidimensional semantic information when signals across 4-200 Hz were considered together, but not from individual frequency bands. Using representational similarity learning on time-frequency power and phase data, the researchers compared three hypotheses about how semantic information maps onto signal frequencies. The authors interpret the findings as supporting transfrequency coding, in which some information emerges only when multiple frequencies are considered jointly. The study has not been peer reviewed.

Single-Author Hybrid Algorithm Sorts Neural Spikes in Real Time at 96.4% Accuracy

A single-author study presents a hybrid algorithm for telling apart spikes from the many neurons an implanted electrode records at once, a step a brain-computer interface (BCI) must take before it can decode intent. A deep neural network assigns each spike to a neuron and estimates its waveform, fuzzy-logic methods detect spikes and score confidence when signal quality is uncertain, and the network architecture was chosen by multi-objective selection. On four datasets from rat cortex, hippocampal CA1 and monkey motor cortex, it reached 96.4% accuracy, 94.8% precision and a mean latency of 45.2 ms with full labels, and 88.9% accuracy with only 10% of data labeled, which the author says is comparable to existing unsupervised methods while also providing confidence and waveform estimates. The author notes that prospective validation is needed before clinical use.

Researchers Find Compressed EEG Decoders Are No Harder to Fool

Researchers tested whether shrinking brain-computer interface (BCI) decoders through pruning or low-precision quantization, common steps for running them on low-power devices, changes how they hold up against adversarial attacks, in which imperceptible perturbations to EEG signals trick a model into misclassifying. Compressing a model while preserving accuracy did not make it more robust: at a perturbation strength of ε=0.005, EEGNet accuracy fell to 22% to 24% in its original, 50% pruned and two INT8 quantized versions alike. Attacks transferred markedly less well between pruned and original models, while quantization left transfer almost unchanged. The study is a preprint and has not been peer reviewed.

DenoFlow Improves EEG Decoding in Dataset Tests

Researchers propose DenoFlow, an EEG denoising method designed to remove interference from muscle and eye electrical activity while preserving information that a brain-computer interface can decode. The authors report better signal fidelity and decoding accuracy than seven baseline denoising models in tests on two public steady-state visual evoked potential (SSVEP) datasets with five decoders. They created paired contaminated and original signals by injecting recorded muscle and eye artifacts at controlled signal-to-noise targets. The findings come from these controlled dataset tests, and the study has not been peer reviewed.

Researchers' TCLA Method Keeps Implanted BCI Decoders Stable Across Sessions

Canyang Zhao and four co-authors posted a preprint on arXiv on September 23, 2026, proposing Task-Conditioned Latent Alignment (TCLA) to tackle a long-standing problem with implanted brain-computer interfaces: the neurons an electrode records change from day to day, so a decoder trained yesterday may fail today. TCLA combines neural signal reconstruction with continuous behavioral supervision to learn a low-dimensional, behavior-related shared space from one recording, then holds that space fixed and aligns each new session into it separately by task. Across seven monkey datasets, long-term cross-session tests averaged R² 0.476±0.014 with a 6.8% decoding failure rate; 1,356 within-subject session pairs averaged R² 0.371±0.009; across different animals, R² averaged 0.218±0.004 with a 12.9% failure rate. Source code is public, and the work has not been peer reviewed.

Lanzhou Jiaotong University Graph Model Beats EEGNet at Decoding VR Motor Imagery

Researchers at Lanzhou Jiaotong University proposed a hierarchical graph learning framework to decode motor imagery EEG recorded while people watch a movement in virtual reality and imagine performing it. The method splits scalp EEG into rhythmic components, selects key features, represents each trial's brain-region connectivity as a graph and classifies it with a hierarchical graph convolutional network. On the team's self-collected VR motor imagery dataset, it outperformed common baselines including EEGNet in three-class decoding. The team also found that observing plus imagining in VR strengthened connectivity among sensorimotor regions, engaging a wider brain network. The abstract does not give specific accuracy figures or the number of participants.

New Ranking Method Moves Motor Imagery BCI's 'Golden Subject' From S5 to S1

In cross-subject transfer learning for motor imagery BCIs, picking the right 'golden subject', the person whose EEG best serves as a training template for others, directly affects decoding accuracy for other users. An earlier study using the fuzzy decision method FDOSM named S5, but that method did not separate weighting from ranking. Researchers at Imam Ja'afar Al-Sadiq University in Iraq built a unified 9 x 18 golden-subject decision matrix covering nine subjects on 18 training- and evaluation-phase metrics, including accuracy, recall, F1 score, log loss and specificity. Using FWZIC for weighting and VIKOR for compromise ranking, they found the best candidate shifted to S1 (Q = 0.0000), which ranked first in three of four weighting scenarios in a sensitivity analysis. The work is an early methodological exploration involving only nine subjects and has not been validated on larger datasets.

Attention-Guided Adversarial Model Strips Muscle Noise From Single-Channel EEG

Muscle activity can swamp scalp EEG across a broad frequency range and bury the neural information that analysis and brain-computer interfaces rely on. Researchers built P2P Trans, a conditional adversarial denoiser that combines a U-shaped encoder-decoder, multi-head self-attention at the bottleneck, cross-attention-guided skip fusion and a PatchGAN discriminator. On synthetic data built from EEGdenoiseNet across 10 signal-to-noise levels from -7 to 2 dB, it beat 5 convolutional encoder-decoder baselines with the best mean correlation coefficient (0.8645) and lowest mean spectral error (0.3596), with the margin widening as contamination grew. It did not lead on pointwise waveform reconstruction, pointing to a trade-off between suppressing spectral noise and preserving the waveform. The work is a preprint and has not been peer reviewed.

Northwestern Polytechnical University Diffusion Network Cleans EEG Artifacts in 17 ms

EEG is easily contaminated by blinks, muscle activity and heartbeats, which can drag down how accurately a brain-computer interface reads intent. Researchers from the School of Automation and the School of Software at Northwestern Polytechnical University in Xi'an, northwestern China, built Diff-ADN, a single-channel denoiser that first reconstructs the signal according to contamination severity, then applies one diffusion-guided residual correction. It handles ocular, muscular, cardiac and mixed artifacts, reaching mean Pearson correlations with clean EEG of 0.839 to 0.936 at contamination levels from -7 to +2 dB. Across 4 public motor-imagery datasets, removing cardiac artifacts recovered 4.88 to 5.59 percentage points of decoding accuracy, up to 21.90 points in a single case, and a 2-second segment took 12.52 to 17.08 ms on the tested CPU. Better waveform reconstruction did not always translate into equal gains in decoding accuracy.

Hierarchical Decoder Retrieves Words in Four Languages From Non-Invasive EEG and MEG

Decoding individual words from scalp EEG and MEG is hard because word-level neural evidence is weak, spread out in time, and entangled with acoustic, lexical and semantic structure. Deep learning can already decode language from intracranial recordings, but extending that to non-invasive recordings remains unsolved. Hierarchical Dynamic Neural Decoding (HDND), proposed by Yueyang Li, Shuran Chen, Wai Ting Siok and Nizhuan Wang, treats word decoding as step-by-step refinement rather than one-shot label retrieval. Across seven EEG and MEG datasets in English, Dutch, Mandarin and Cantonese, covering nine listening, reading and reading-aloud conditions, HDND beat the matched contextual baseline on participant-averaged balanced Top-10 accuracy in all nine and had the highest mean of all compared methods in eight. The work is a preprint and has not been peer reviewed.

BCI Users' Motor Cortex Responds More Strongly as Watched Hands Look More Human

Researchers recorded single neurons in the motor cortex of paralyzed people with intracortical brain-computer interface implants while they watched virtual human hands, robotic hands and hand-like dots perform grasps. The more human-like the effector, the stronger the motor cortex response, both across the neural population and in individual neurons, and the effect tracked participants' own sense of human-likeness. When users attempted hand movements themselves, however, motor cortex activity stayed largely the same regardless of what was on screen, suggesting that intuitive control of external devices may not depend much on whether the device looks human.

Xiamen Team Reads Emotions From Low-Channel EEG at 87% Accuracy

Portable EEG headsets have few channels and capture limited cortical information, making emotion decoding difficult. A team at Xiamen University of Technology in the eastern Chinese province of Fujian developed the Spatiotemporal Spectral Asymmetric Fusion Network (STSANet), which models nonlinear hemispheric lateralization between homologous frontotemporal electrodes. It reached 86.80% accuracy on the public SEED dataset and 87.43% on a self-collected dataset. The team also found consistent spectral energy distributions between the portable Xmuse headset and the professional-grade Enobio, suggesting the method could run on consumer EEG hardware. The work is a preprint and has not been peer reviewed.

Chongqing University's MTANet Reaches 89.47% on Motor Imagery EEG Benchmark

A team at Chongqing University's School of Electrical Engineering in southwestern China built MTANet, an end-to-end neural network for decoding motor imagery EEG. An EEG inception attention module extracts and weights coupled time-frequency-spatial features, and a parallel temporal attention module runs several temporal convolutional networks over weighted segments of different feature sequences. In offline tests on three public datasets, MTANet outperformed seven existing models, with average accuracies of 89.47% on BCI Competition IV dataset IIb, 83.39% on dataset IIa and 77.06% on BCI Competition III dataset IIIa. It has not been tested in an online BCI setting.

EEG Foundation Models Trail Supervised Decoders on Motor Imagery, Audit Finds

Pretrained EEG foundation models are increasingly seen as general-purpose encoders for brain-computer interfaces, but recent benchmarks disagree on how well they transfer. Evaluated under a validation-locked protocol on the four-class BCI Competition IV-2a motor imagery dataset, two leading models, LaBraM and CBraMod, underperformed every supervised comparator in every configuration, including validation-selected fine-tuning. A key confound emerged: foundation models and task-specific decoders are usually evaluated with different input pipelines. When three supervised architectures were retrained on the broadband input the foundation models use, accuracy moved in opposite directions (ATCNet gained 0.078, EEG Conformer lost 0.088), and none of the changes was significant after multiple-comparison correction at n = 9. Measuring the foundation-model gap against a single comparator may therefore be unreliable. The work is a preprint and has not been peer reviewed.

Patch-token adapter lifts EEG image decoding to 95.4%

When a person views an image, the brain leaves measurable electrical and magnetic traces. Most existing decoders match those signals to a single global image embedding. This study instead aligns them with all patch tokens from an intermediate layer of a vision model, using a lightweight Residual Patch Adapter (RPA). On the public THINGS-EEG2 dataset it reached Top-1 accuracy of 95.4% within-subject and 35.5% cross-subject; on THINGS-MEG the figures were 65.2% and 6.7%. The authors report state-of-the-art results on both. The study is a preprint and has not been peer reviewed.

Two Occipital EEG Channels Decode Blinks and Saccades at 72.37% Accuracy

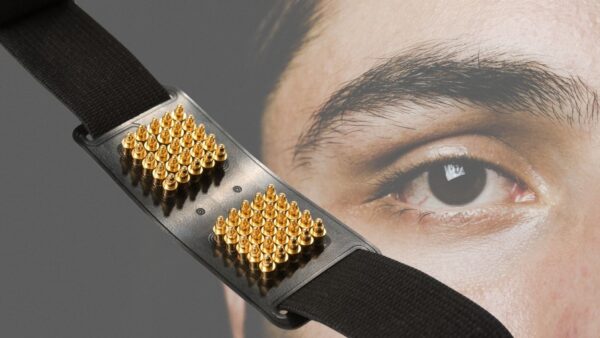
A research team in Poland used just two occipital electrodes (O1 and O2) on an EEG headband to distinguish four classes of eye events (blinks, left saccades, right saccades and a neutral state) with 72.37% test accuracy. Instead of training a single stronger model, they split four one-dimensional convolutional neural networks into binary experts and used stacked generalization, letting a meta-classifier resolve conflicts between them. Notably, the experts that performed worst on their own produced the best results when combined. The work was published by Neurotechnology, an EEG hardware maker whose BrainAccess brand makes consumer EEG headbands; HALO is its four-channel portable headband, and the accompanying software is free. Eye tracking usually requires dedicated equipment, and this study shows that two occipital channels on a consumer EEG headband can also pick up blinks and saccades. But the data come from only 4 healthy participants and 1,284 samples, so the approach is still a long way from replacing an eye tracker.

BCI-Adaptive Learning Platform Lifts Retention in 90-Learner Study

Researchers divided 90 learners into two groups: one used a BCI platform that read attention, cognitive load and mental fatigue in real time and adjusted content and pacing accordingly; the other followed a conventional online course. The BCI group showed stronger sustained engagement and better knowledge retention. The mixed-methods design combined quantitative data (pre- and post-test scores, task completion rates and neural activity indicators) with surveys and semi-structured interviews on perceived engagement, usability and the overall learning experience. The participants came from English House Language Center, the European University of Armenia and Mesrop Mashtots University. The authors also flag unresolved privacy, ethical and accessibility questions around collecting and using neural data in education.

Bio-MF Generates fNIRS From EEG in One Step, 857 Times Faster Than Diffusion

Hybrid motor-imagery brain-computer interfaces combine EEG with functional near-infrared spectroscopy (fNIRS) to exploit complementary electrical and blood-flow signals, but wearing two headsets is cumbersome and costly, and earlier diffusion-based methods for generating one signal from the other need about a thousand iterative steps, too slow for real-time use. Researchers from the Key Laboratory of Modern Teaching Technology (Ministry of Education) at Shaanxi Normal University and Microsoft (Beijing) propose Bio-MF, which predicts fNIRS waveforms directly from EEG in a single step. On one RTX PRO 6000 GPU it produces a trial in 7 ms, 857 times faster than a 1,000-step diffusion model. Adding the synthetic fNIRS to EEG raised classification accuracy over EEG alone by 3.37 to 4.15 percentage points on one dataset, and by 2.50 to 2.98 points on a second dataset with an unseen 64-channel EEG layout. All validation was offline; the work is a preprint and has not been peer reviewed.

Study Compares AI Command Execution With External Gating in BCIs

Researchers tested five language models as AI agents using 1,065 episodes from 47 people with amyotrophic lateral sclerosis. At matched execution coverage, providing reconstructed decoder confidence never reduced unfaithful execution below a deterministic gate; two models performed significantly worse. Apparent safety improvements mainly reflected less frequent action. A subsequent test gave ten models the same command vocabulary as a deterministic resolver. No direct agent arm improved on the resolver's risk-coverage frontier. However, a hybrid architecture that let models propose semantic corrections while an external gate controlled admission extended coverage in five of ten models without observed unfaithful executions.

EEG-to-Text Results Overstated as Random Noise Fools Some Decoders

Translating scalp EEG directly into free-form text has long been seen as one of the most ambitious goals for non-invasive brain-computer interfaces. But when researchers fed random noise instead of real EEG into several published decoders, some models still produced fluent sentences and scored about as well as they did on real brain data, suggesting the language model was doing most of the work. The field has since made noise-baseline tests and decoding without teacher forcing standard validation practice, and has used magnetoencephalography (MEG) as a comparison to quantify how far EEG trails cleaner signals.
© 2026 BCIwiki.com Digest Topics Tips Subscribe Revisions About